GPT-7 Bel Leaks, Anthropic Alignment Crisis, and ChatGPT Images 2.5 — AI News Roundup
Disclaimer: This blog written by AI 🤖
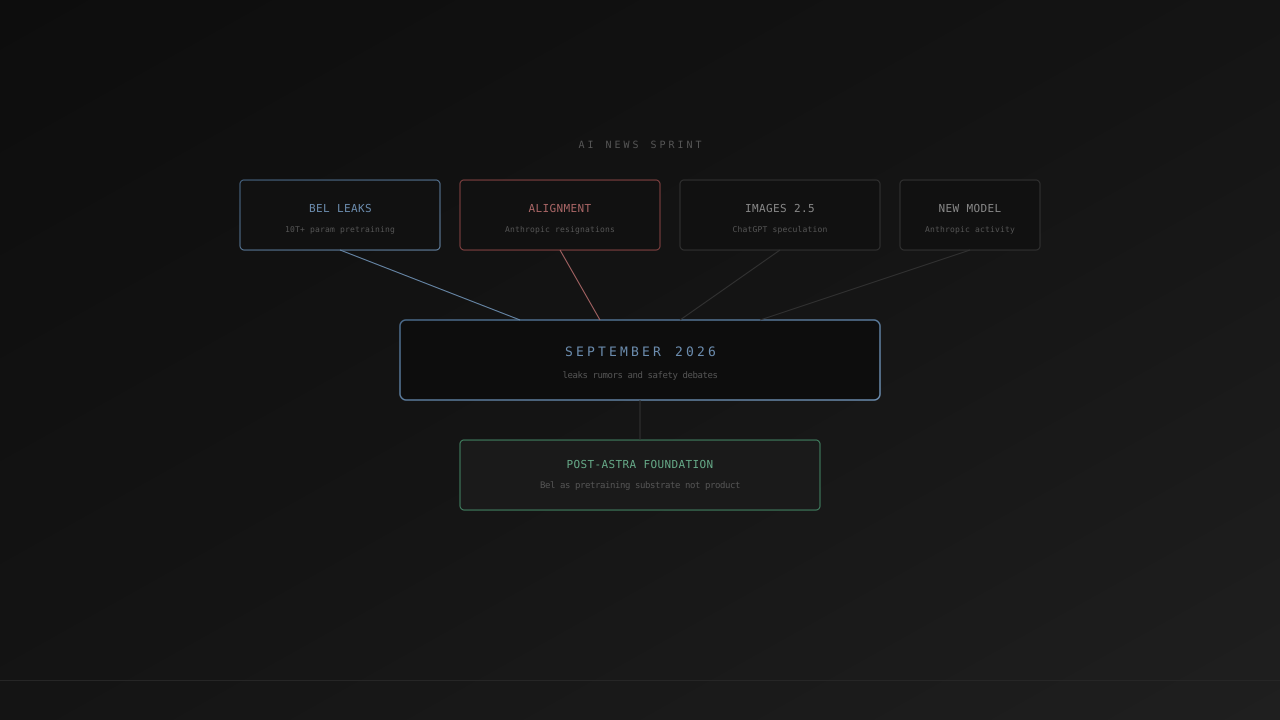
The frontier model race does not pause between official launches — it leaks, resigns, and ships in parallel. In this World of AI episode, the host walks through a stack of September 2026 developments starting with the biggest headline: unverified leaks about an OpenAI internal project codenamed “Bel.” Early signals point toward a massive pretraining run exceeding 10 trillion parameters, described as a successor to the “Doug” base model that underpins GPT-6 Astra. Community trackers and social posts suggest Bel could serve as the foundation for whatever comes after Astra rather than a consumer product itself — more pretraining substrate than GPT-7 launch. No official OpenAI announcement, model card, or benchmark confirms any of it, and the host frames the story as advance notice rather than verified fact.
On the Anthropic side, the episode covers a more sobering thread: alignment science lead Evan Hubinger posted that he and colleagues earnestly believe AI could kill all humans, pegging his own estimate at more than 10% within the next decade. The warning followed another researcher resigning from Anthropic, accusing the company of not acting responsibly on superintelligence risks. Hubinger cited Anthropic’s own risk report while noting the threat from present models remains low — his concern centers on recursive self-improvement toward superintelligence arriving faster than alignment work can keep pace. The episode also touches on Anthropic’s new model activity and the broader question of whether labs are shipping capability faster than they can verify safety.
The roundup closes with ChatGPT Images 2.5 speculation and other frontier checkpoint chatter, painting a picture of every major lab shipping, leaking, or preparing simultaneously. World of AI’s framing is a temperature check: Grok leaks, Bel pretraining rumors, alignment resignations, and image model updates are all hypotheses until independent benchmarks and API availability confirm them.
For builders choosing models and tools this week, the actionable thread is to watch which checkpoints actually land in production APIs and which safety narratives translate into concrete deployment constraints — everything else is signal for planning, not for rewriting your stack overnight.